

Hardware · Home Automation · Reverse Engineering · Local AI
Own your hardware
We tear down, measure, document and publish. Consumer hardware/software projects, reverse engineering, Home Assistant home automation, local AI and self-hosted inference.
Système d'irrigation Zigbee sous Home Assistant — 3 zones, 100% local
Automatisez l'arrosage de vos plantes avec un commutateur Zigbee 4 canaux, des pompes DC, des capteurs d'humidité Tuya et Home Assistant. Gestion multi-zones, seuils configurables, mode automatique et supervision complète.
 fabz 🧪 🧠 🌱 🏅 127
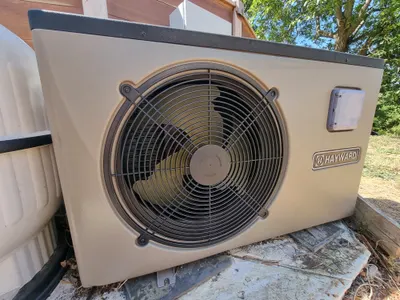
Piloter une PAC Hayward en wifi avec un ESP32-S3 sous Home Assistant
Comment connecter une pompe à chaleur Hayward de piscine à Home Assistant via un ESP32-S3 Zero, un module RS485 et ESPHome. Guide complet : hardware, soudure, sniffing Modbus, YAML et intégration Lovelace.
fabz 🧪 🧠 🌱 🏅 128 
Fabriquer un capteur de CO2 Zigbee avec ESP32-H2 et MH-Z19 pour Home Assistant
Guide complet pour construire un capteur de CO2 Zigbee avec un ESP32-H2 Super Mini, un capteur MH-Z19 et une LED RGB. Firmware Arduino, intégration Zigbee2MQTT et carte Lovelace pour Home Assistant.
fabz 🧪 🧠 🌱 🏅 2 128 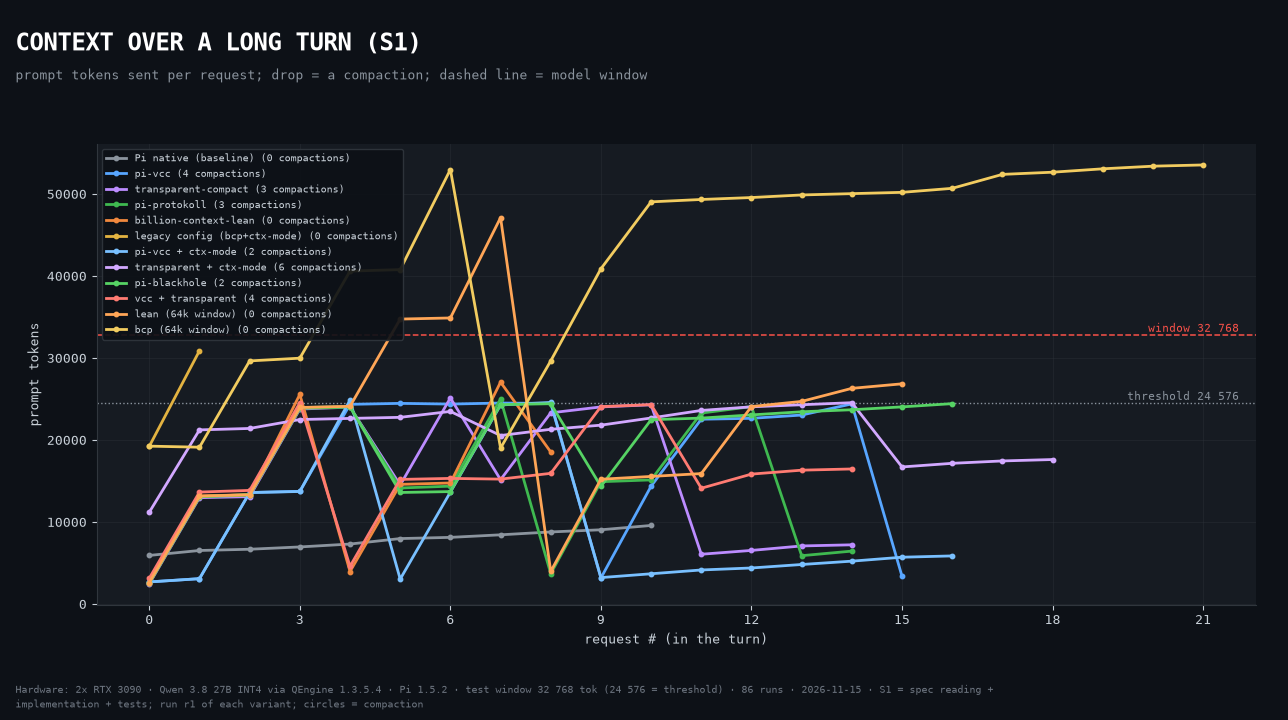
Memory management for local Qwen 27B: pi-blackhole, pi-vcc, pi-protokoll, billion-context or transparent-compact?
My Qwen 27B sessions were dying without any error message: empty response, turn cut off in the middle of a tool batch, "EMERGENCY" alerts up to 246% of the window. I audited 248 real sessions, then built a reproducible bench to compare 10 memory-management configurations (compaction, i.e. the automatic summarization of context when the window fills up) under Pi. All of them run on the same model: Qwen 27B INT4 served by QEngine on 2 RTX 3090s, 262k window.
- en
- fr
fabz 🧪 🧠 🌱 🏅 1 37 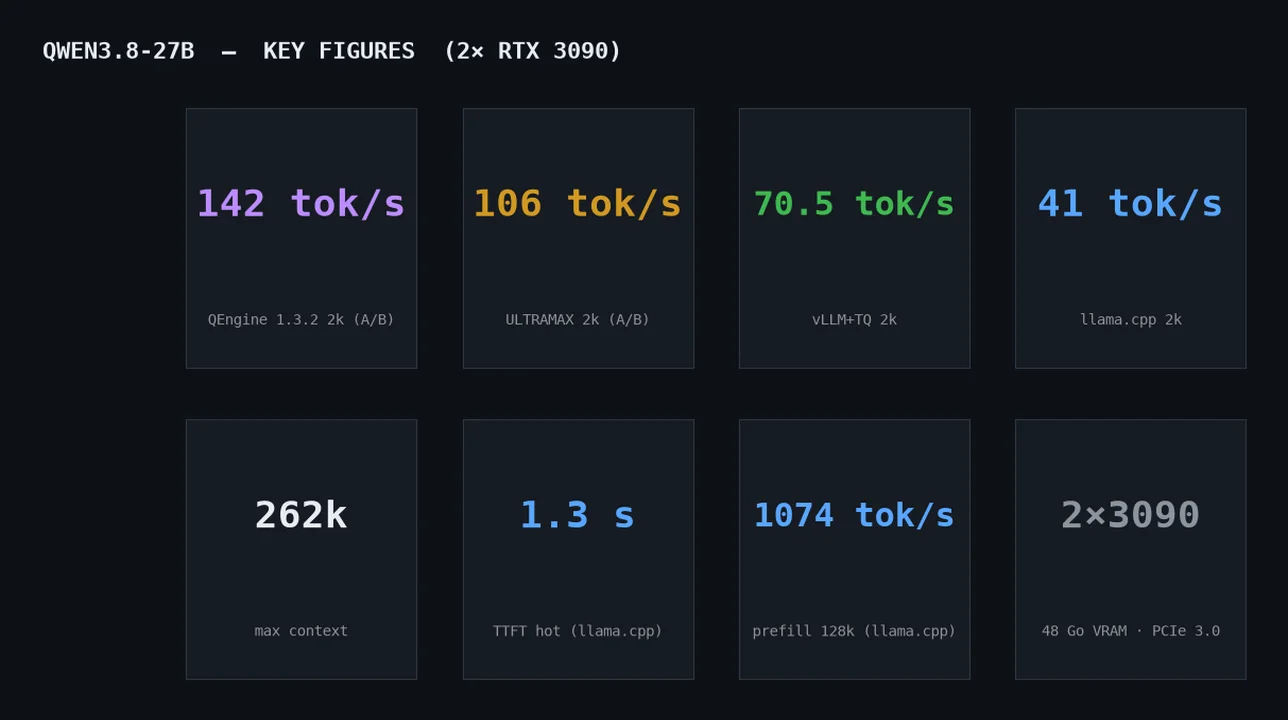
Qwen 3.8 27B on 2 RTX 3090s + 128GB of RAM: QEngine, ULTRAMAX, vLLM or llama.cpp?
I compared 4 engines for Qwen 3.8 27B, the dense version of the model, on my machine: 2 RTX 3090s with 24 GB each, 128 GB of RAM and PCIe 3.0. Everything comes from my bench, with the same prompts. Two caveats, which I repeat each time: the figures don’t all come from the same session, and the comparison is not at equal quantization.
- en
- fr
fabz 🧪 🧠 🌱 🏅 70 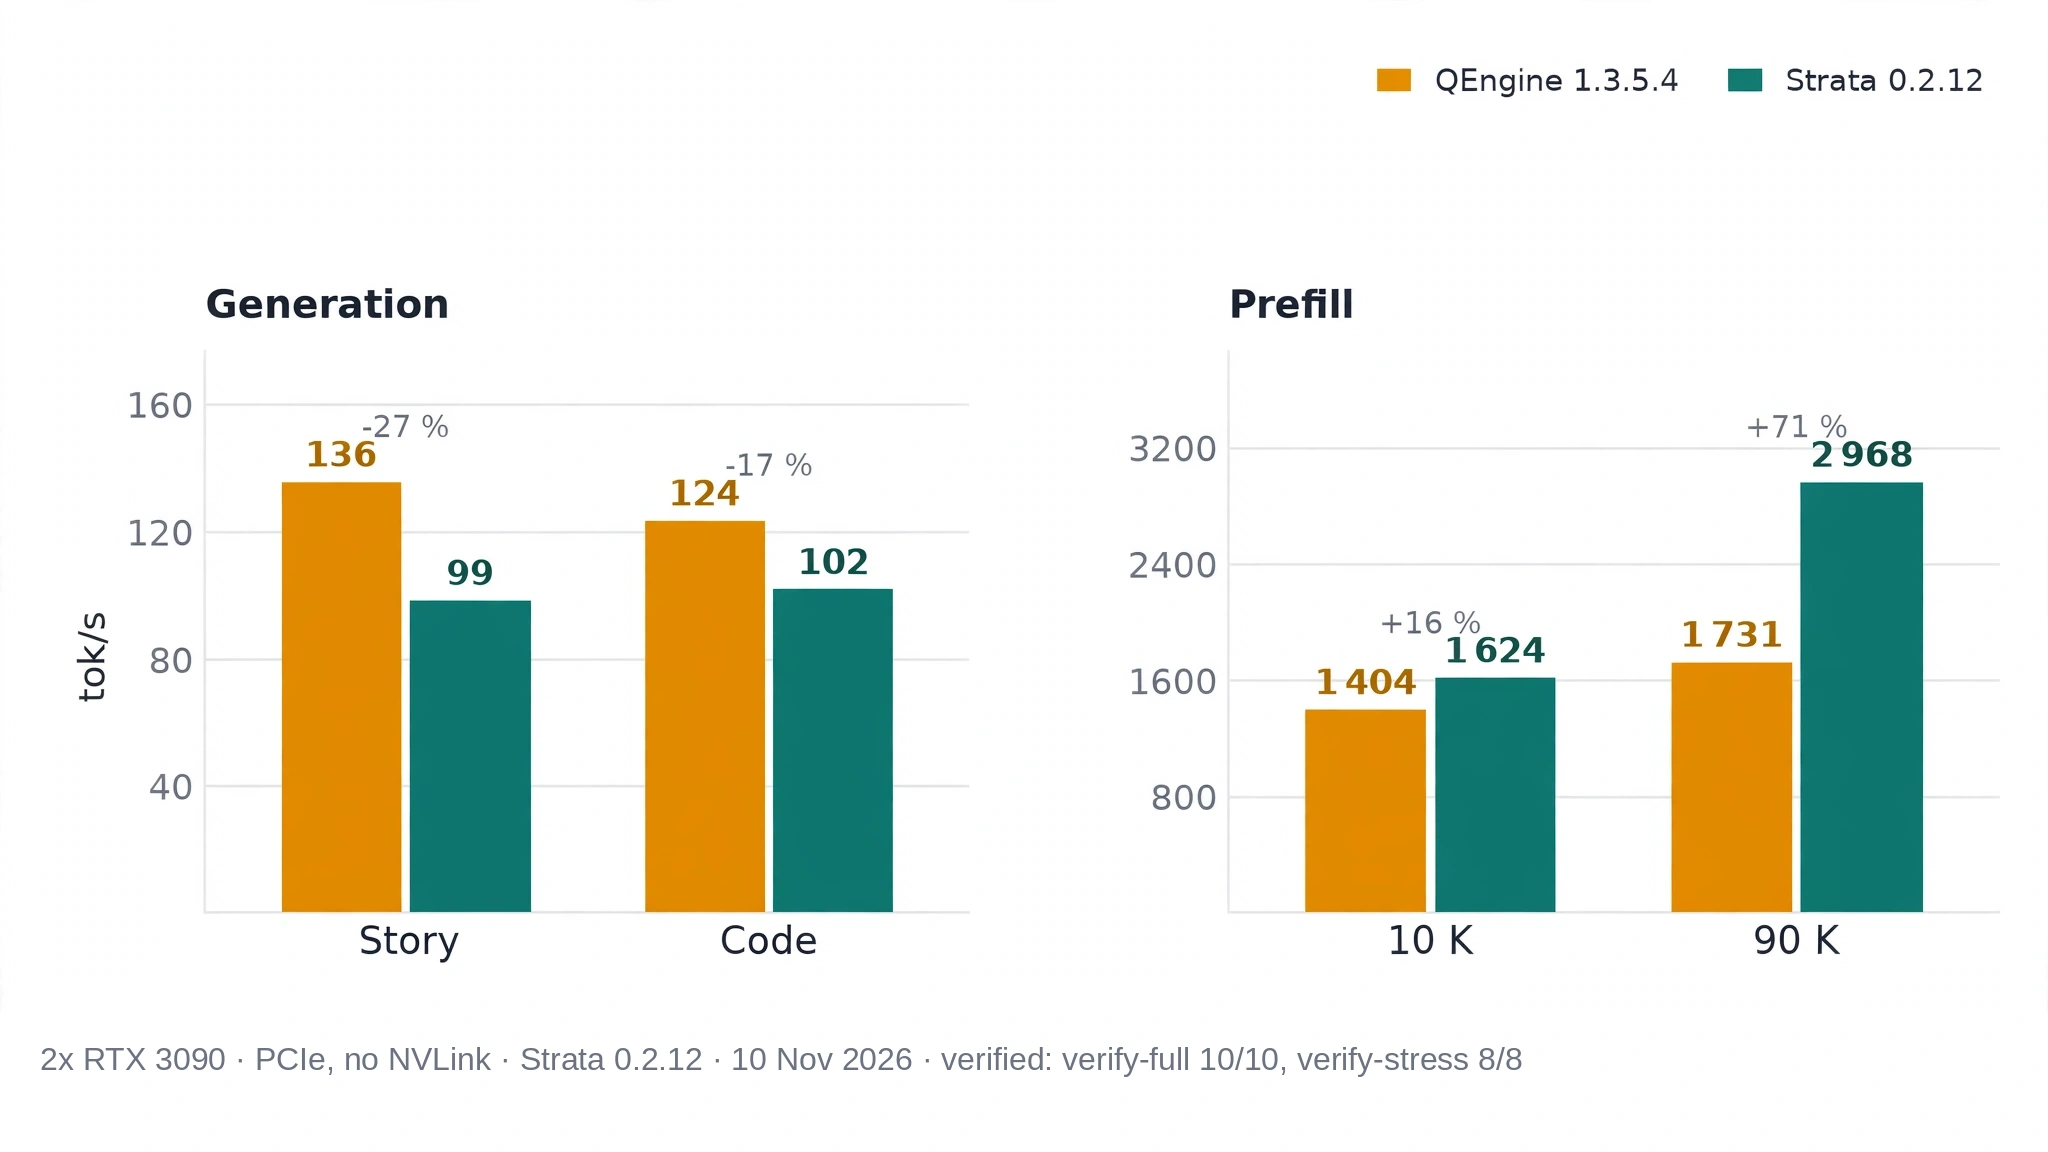
Qwen 3.8 Flash Next on 2 RTX 3090s + 128 GB of RAM: QEngine, Strata, vLLM or llama.cpp?
I was torn between these 4 engines for running Qwen 3.8 Flash Next (QFN) on my machine: 2 RTX 3090s with 24 GB each, 128 GB of RAM and PCIe 3.0. I measured QEngine and Strata myself. For vLLM and llama.cpp, I rely on figures published by others on 2×3090 rigs.
- en
- fr
fabz 🧪 🧠 🌱 🏅 90 